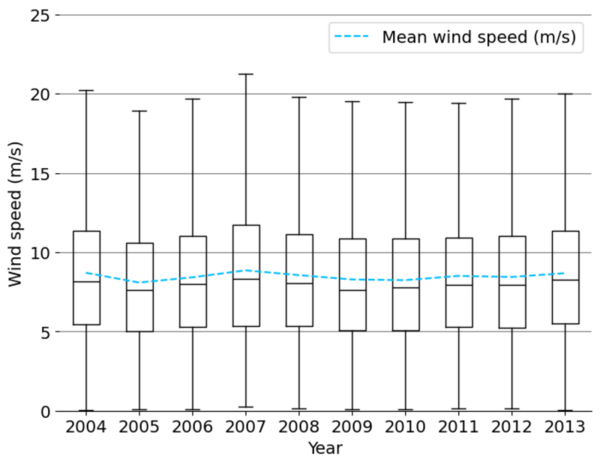
The authors looked at the feasibility to predict wind speeds that will have less reliance on using historical data.
Read More...Evaluating the effectiveness of synthetic training data for day-ahead wind speed prediction in the Great Lakes
The authors looked at the feasibility to predict wind speeds that will have less reliance on using historical data.
Read More...Predicting smoking status based on RNA sequencing data
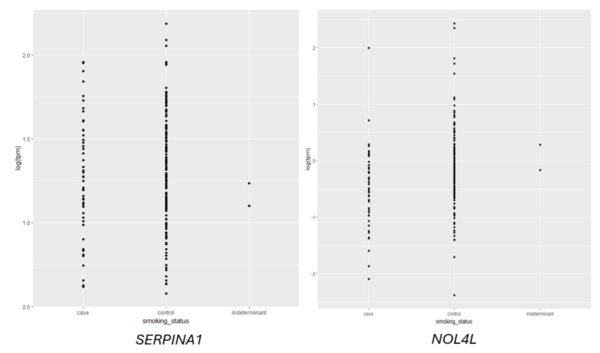
Given an association between nicotine addiction and gene expression, we hypothesized that expression of genes commonly associated with smoking status would have variable expression between smokers and non-smokers. To test whether gene expression varies between smokers and non-smokers, we analyzed two publicly-available datasets that profiled RNA gene expression from brain (nucleus accumbens) and lung tissue taken from patients identified as smokers or non-smokers. We discovered statistically significant differences in expression of dozens of genes between smokers and non-smokers. To test whether gene expression can be used to predict whether a patient is a smoker or non-smoker, we used gene expression as the training data for a logistic regression or random forest classification model. The random forest classifier trained on lung tissue data showed the most robust results, with area under curve (AUC) values consistently between 0.82 and 0.93. Both models trained on nucleus accumbens data had poorer performance, with AUC values consistently between 0.65 and 0.7 when using random forest. These results suggest gene expression can be used to predict smoking status using traditional machine learning models. Additionally, based on our random forest model, we proposed KCNJ3 and TXLNGY as two candidate markers of smoking status. These findings, coupled with other genes identified in this study, present promising avenues for advancing applications related to the genetic foundation of smoking-related characteristics.
Read More...Effects of different synthetic training data on real test data for semantic segmentation
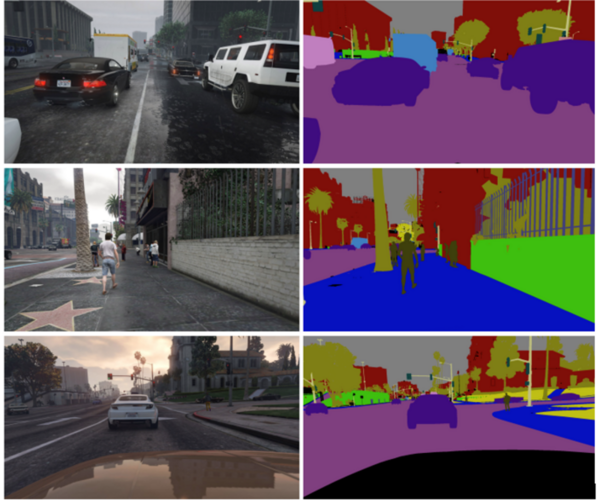
Semantic segmentation - labelling each pixel in an image to a specific class- models require large amounts of manually labeled and collected data to train.
Read More...Heat conduction: Mathematical modeling and experimental data
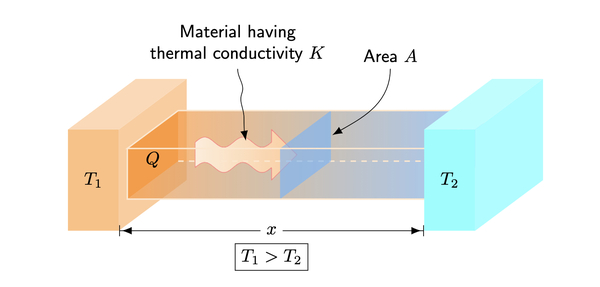
In this experiment, the authors modify the heat equation to account for imperfect insulation during heat transfer and compare it to experimental data to determine which is more accurate.
Read More...LawCrypt: Secret Sharing for Attorney-Client Data in a Multi-Provider Cloud Architecture
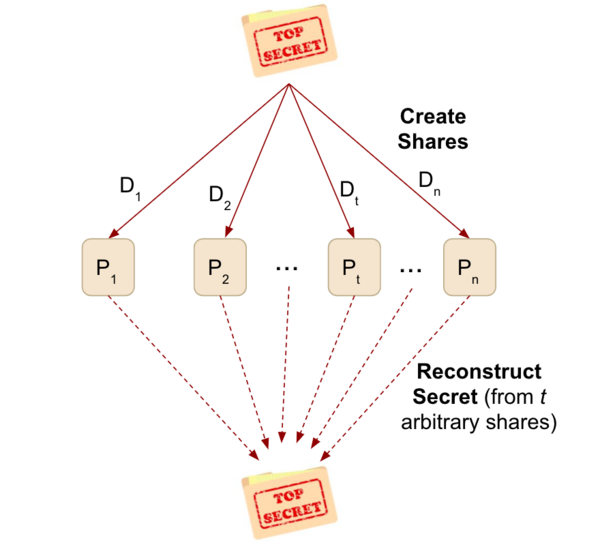
In this study, the authors develop an architecture to implement in a cloud-based database used by law firms to ensure confidentiality, availability, and integrity of attorney documents while maintaining greater efficiency than traditional encryption algorithms. They assessed whether the architecture satisfies necessary criteria and tested the overall file sizes the architecture could process. The authors found that their system was able to handle larger file sizes and fit engineering criteria. This study presents a valuable new tool that can be used to ensure law firms have adequate security as they shift to using cloud-based storage systems for their files.
Read More...Understanding the impossibility of machine learning fairness with data examples
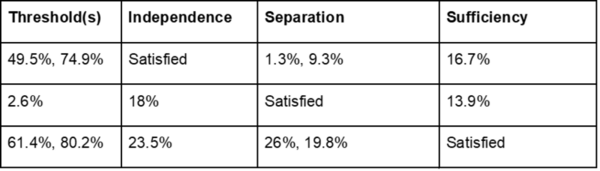
Machine learning systems are often expected to make fair decisions, yet the most widely used fairness criteria—independence, separation, and sufficiency—cannot generally be satisfied at the same time. In this study, students tested these criteria using a logistic regression model on a real-world student performance dataset and found that each criterion was met only at different prediction thresholds, with no threshold satisfying all three simultaneously. These results illustrate the inherent trade-offs in algorithmic fairness and highlight why achieving perfectly fair machine learning models is often impossible in practice.
Read More...Mitigating skin color bias in dermatology AI using CycleGAN-based data augmentation
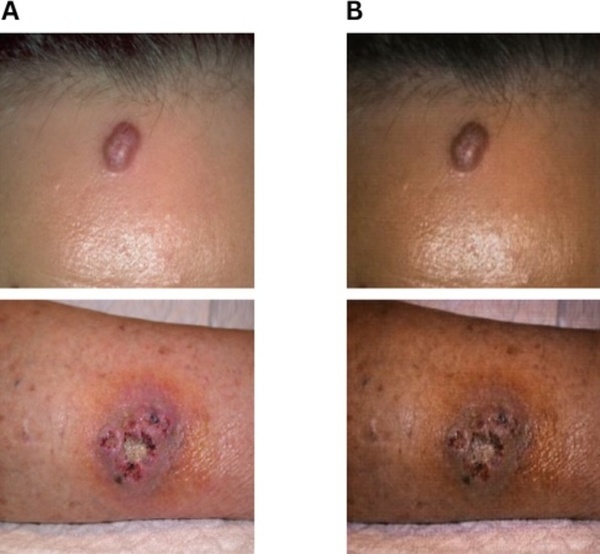
This study investigates skin tone bias in artificial intelligence models used for dermatological disease classification and evaluates a CycleGAN-based data augmentation approach to improve diagnostic performance on darker skin types. We generated synthetic dark-skinned images to enhance dataset diversity and compared model performance before and after augmentation. The results demonstrate that augmentation with synthetic dermatological images can help reduce disparities in diagnostic performance across skin tones, highlighting a practical strategy for improving fairness in dermatology AI systems.
Read More...Using text embedding models as text classifiers with medical data
This article describes the classification of medical text data using vector databases and text embedding. Various large language models were used to generate this medical data for the classification task.
Read More...Exploring the effects of diverse historical stock price data on the accuracy of stock price prediction models
Algorithmic trading has been increasingly used by Americans. In this work, we tested whether including the opening, closing, and highest prices in three supervised learning models affected their performance. Indeed, we found that including all three prices decreased the error of the prediction significantly.
Read More...Lung cancer AI-based diagnosis through multi-modal integration of clinical and imaging data
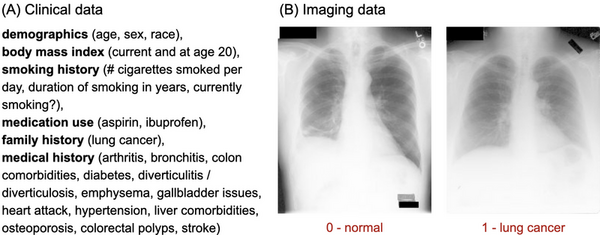
Lung cancer is highly fatal, largely due to late diagnoses, but early detection can greatly improve survival. This study developed three models to enhance early diagnosis: an MLP for clinical data, a CNN for imaging data, and a hybrid model combining both.
Read More...